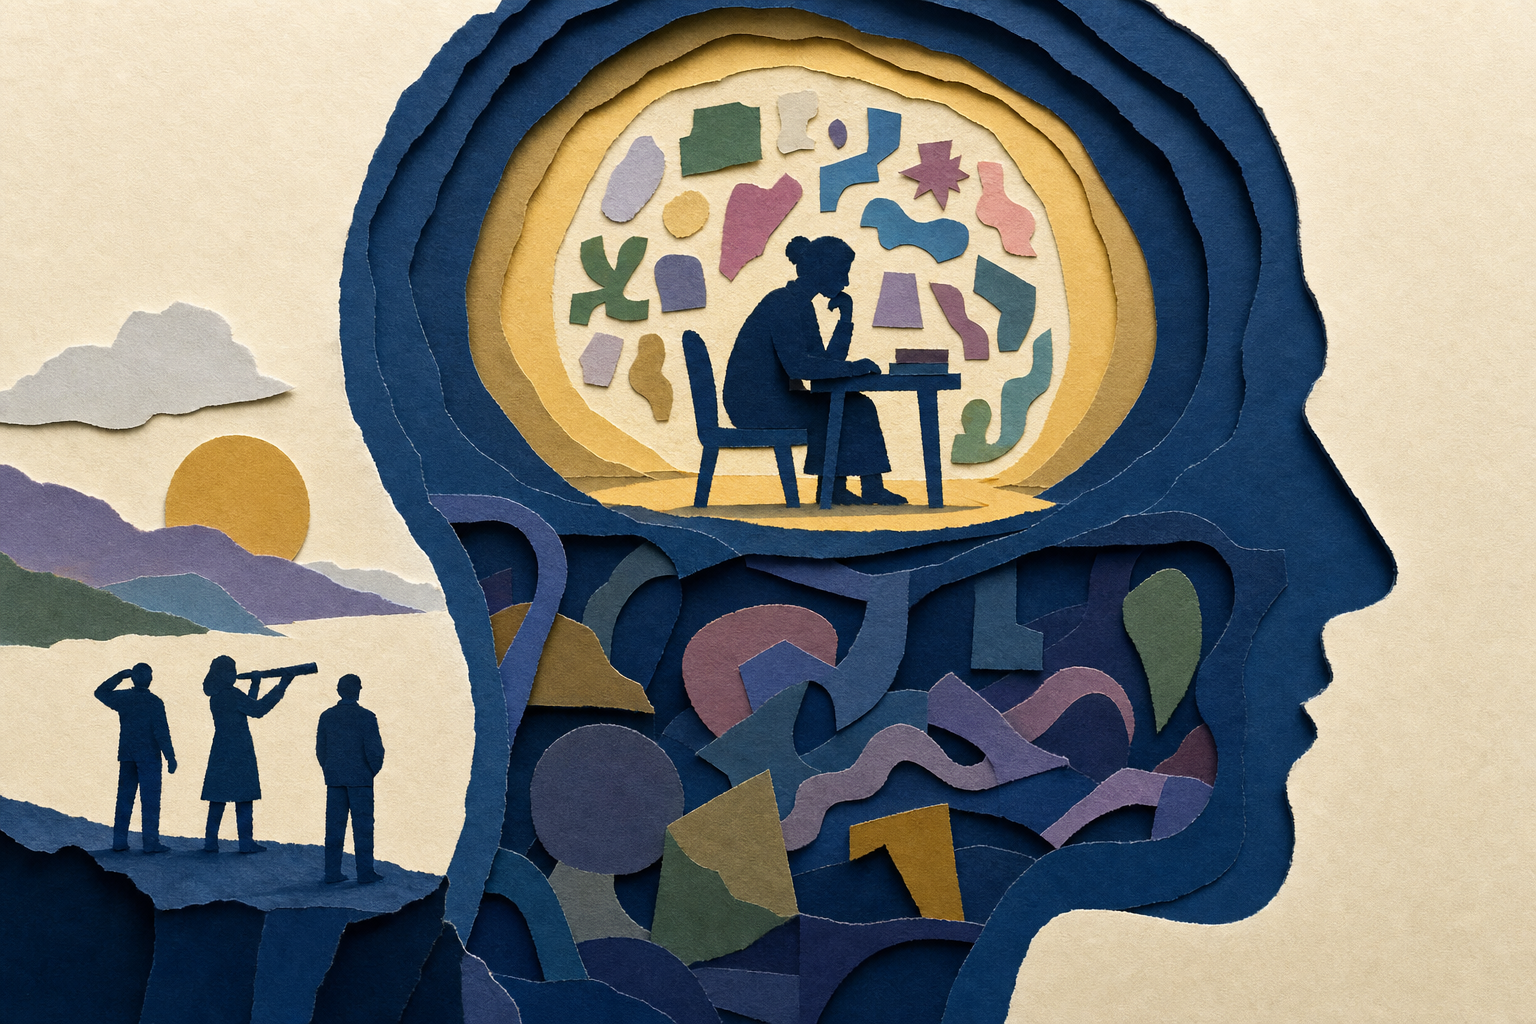
On July 6, 2026, Anthropic published interpretability research reporting the discovery of a functional workspace inside its Claude language model, dubbed "J-space," that holds and manipulates thoughts which never appear in the model's output. Using a new technique called the Jacobian lens (J-lens), the company mapped internal activations to "the words most likely to be output next," showing that the resulting set of vectors forms a single shared workspace within the model. The structure resembles the global workspace theory in neuroscience — the hypothesis of a shared workspace in the brain responsible for conscious access.
Continue reading
The rest of this article is for AI News Blitz readers. Choose an option below to keep reading.
Already purchased? Sign in✓ Signed in — this article isn’t included in your current plan.
Unlocking the full article...
Contact us
Questions, corrections, or ideas? Send us a message here. We aim to reply by email within 24 hours.
Thank you. Your message has been sent. We aim to reply by email within 24 hours.Please enter your email address and a message.We could not send your message. Please try again in a little while.