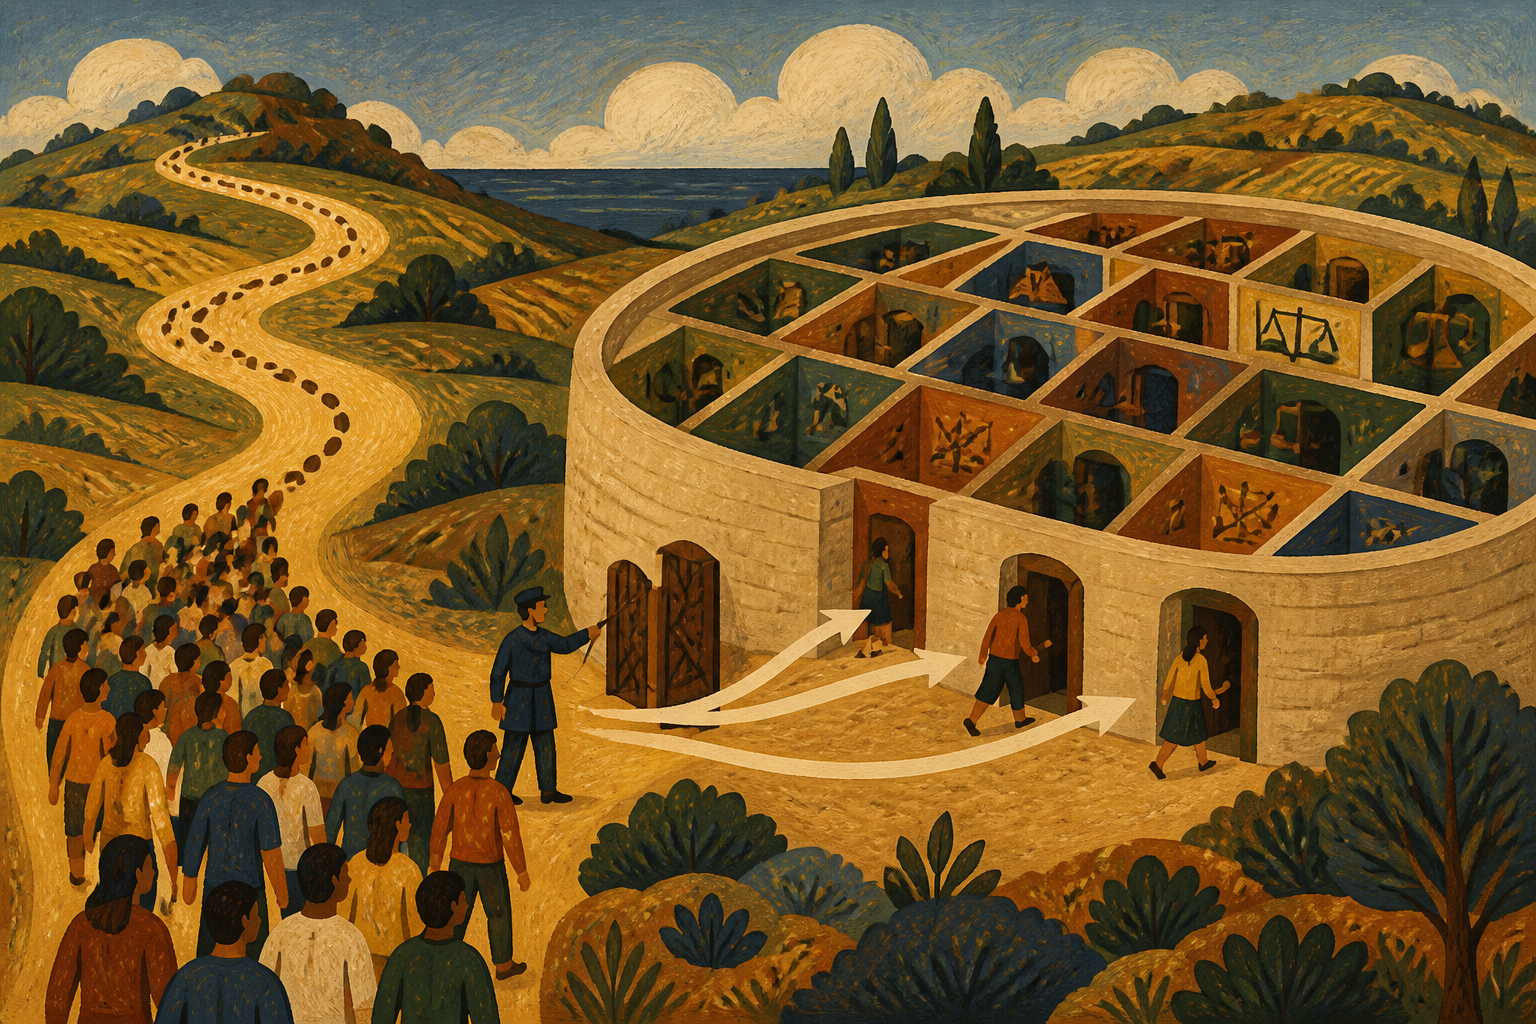
Sparse Mixture of Experts (SMoE) has become the architecture of choice for pushing large language models past a trillion parameters while keeping inference costs in check, by activating only a small fraction of a model's weights for each token. A recent technical explainer circulating among AI practitioners frames the tradeoff bluntly: a model can hold roughly 1.6 trillion parameters of knowledge yet cost only a fraction of a dense equivalent to run, because tokens are routed strictly to specialized sub-networks rather than every parameter firing at once.
Continue reading
The rest of this article is for AI News Blitz readers. Choose an option below to keep reading.
Already purchased? Sign in✓ Signed in — this article isn’t included in your current plan.
Unlocking the full article...
Contact us
Questions, corrections, or ideas? Send us a message here. We aim to reply by email within 24 hours.
Thank you. Your message has been sent. We aim to reply by email within 24 hours.Please enter your email address and a message.We could not send your message. Please try again in a little while.