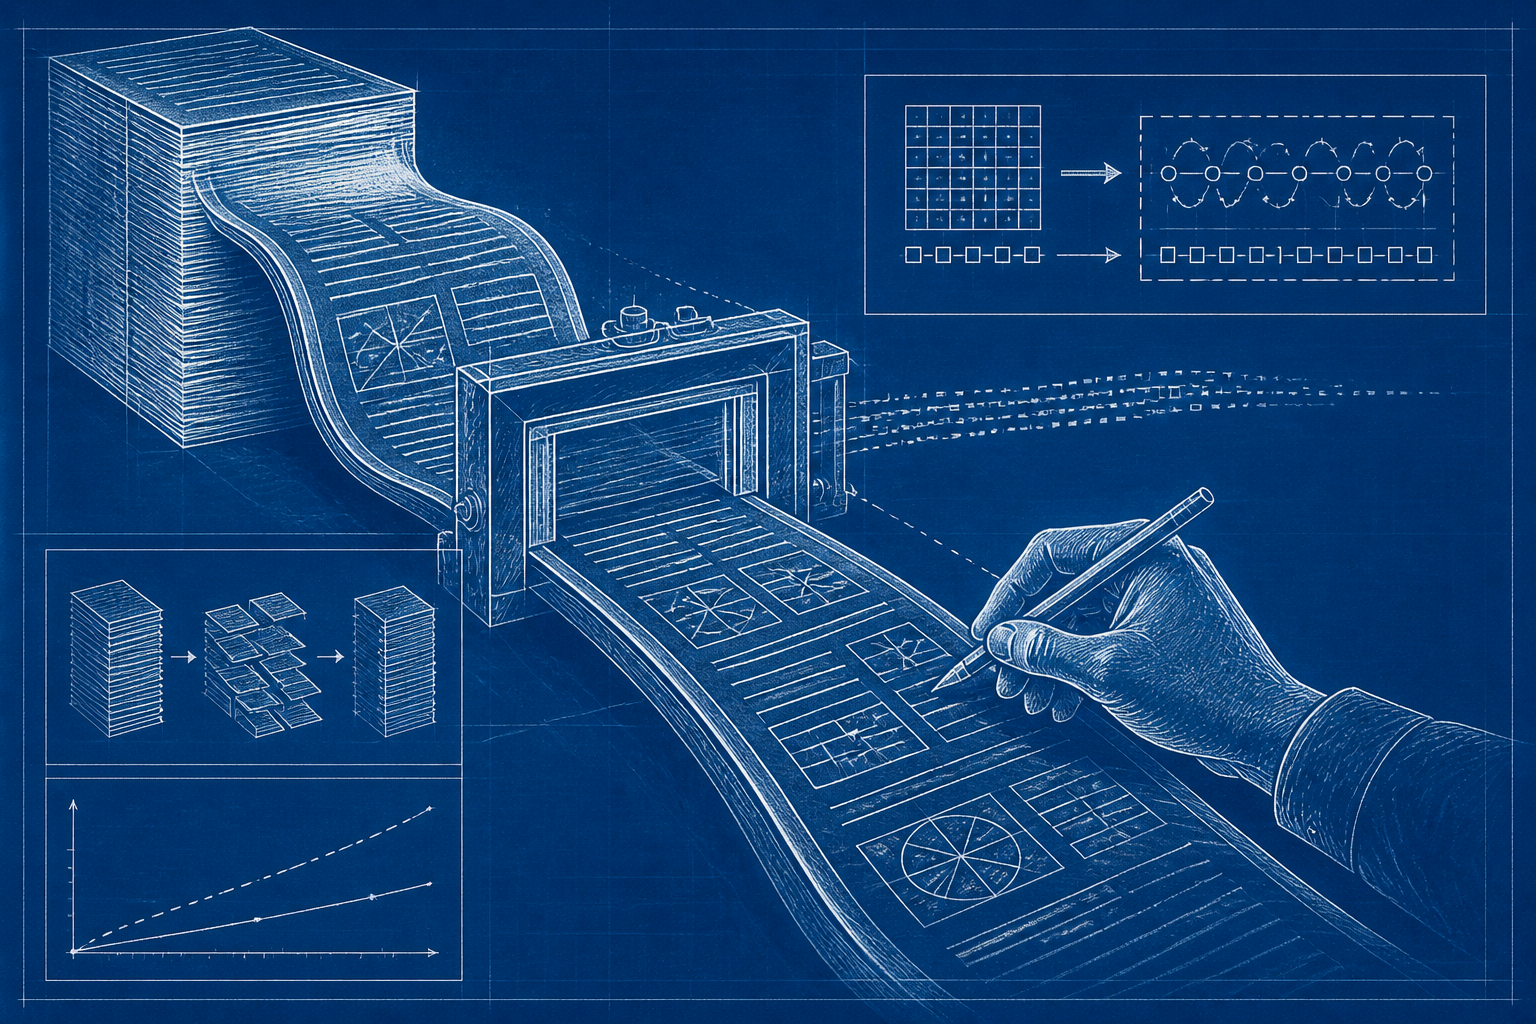
Baidu has released Unlimited-OCR, an MIT-licensed 3-billion-parameter document model that can read an entire multi-page PDF in one forward pass on local hardware, sidestepping the page-by-page chunking that has long constrained end-to-end OCR. The model, published on June 22, 2026, targets a stubborn bottleneck in machine reading: how to process long documents without runaway memory use or degraded accuracy as output length grows.
Continue reading
The rest of this article is for AI News Blitz readers. Choose an option below to keep reading.
Already purchased? Sign in✓ Signed in — this article isn’t included in your current plan.
Unlocking the full article...
Contact us
Questions, corrections, or ideas? Send us a message here. We aim to reply by email within 24 hours.
Thank you. Your message has been sent. We aim to reply by email within 24 hours.Please enter your email address and a message.We could not send your message. Please try again in a little while.